Darija Word2Vec
Word embeddings trained for low-resource Moroccan Arabic (Darija) NLP.
3M
of an 8.7M-sentence corpus trained
~33K
sentences / min throughput
~90 min
total training time
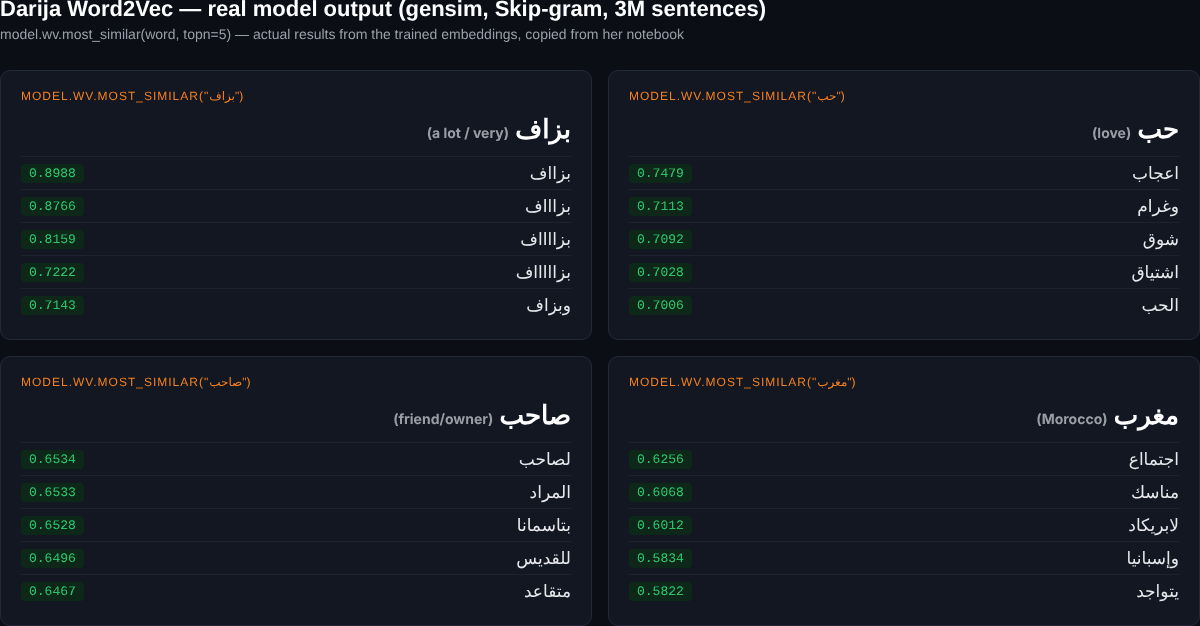
One of the first large-scale word embedding models for Darija, a language with very little NLP tooling.
01
Skip-gram with negative sampling on 3M Darija sentences
02
Captures semantic neighbours in a language with little NLP tooling
03
Pairs with darija-gap as a Darija NLP project set